Products

Jul 25, 2026
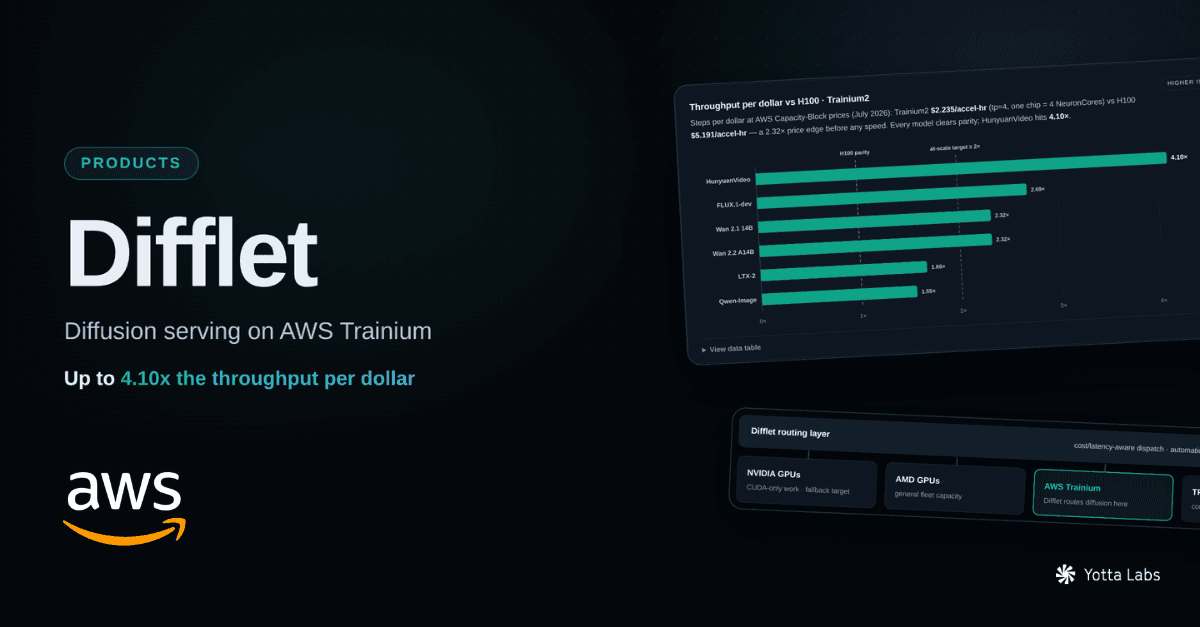
Difflet: Serving Diffusion Models on AWS Trainium
Difflet runs six production image and video diffusion models end to end on AWS Trainium, with up to 4.10x the throughput per dollar of an H100.

FEATURED POSTS
Products

Jul 25, 2026
Difflet: Serving Diffusion Models on AWS Trainium
Difflet runs six production image and video diffusion models end to end on AWS Trainium, with up to 4.10x the throughput per dollar of an H100.
Inference

Mar 17, 2026
Mini-SGLang-Neuron: Bringing Lightweight LLM Inference to AWS Trainium and Inferentia
A lightweight inference framework integrating SGLang with AWS Neuron to enable efficient LLM serving on Trainium and Inferentia across multi-hardware environments.
Products

Feb 06, 2026
Launch Templates: Infrastructure Portability for Production AI
AI infrastructure should not dictate how you build models.
News

Jan 16, 2026
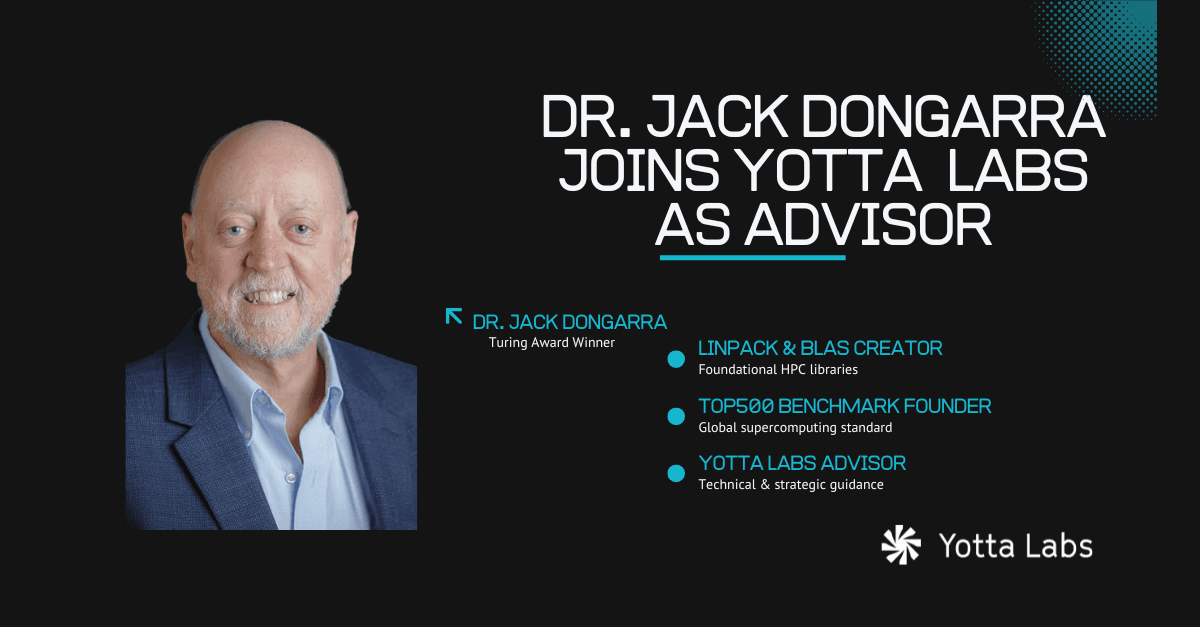
Yotta Labs Welcomes Jack Dongarra: A Signal for the Next Era of AI Infrastructure
Dr. Jack Dongarra, 2021 ACM A.M. Turing Award recipient and architect of modern performance benchmarking, has joined Yotta Labs as a Technical & Strategic Advisor. As AI infrastructure reaches a new inflection point, Yotta Labs is applying decades of hard-won HPC lessons to build an intelligent orchestration layer for scalable, interoperable GPU systems.
News

Jan 05, 2026
Academic Research Credit Support Program Launch
Artificial intelligence research is advancing at an unprecedented pace — yet access to scalable, reliable compute remains one of the biggest constraints facing researchers today. Across universities, research labs, and independent research communities, ambitious ideas are often slowed by limited GPU availability, high infrastructure costs, and rigid cloud environments not designed for experimentation. Researchers are forced to make tradeoffs: smaller models, fewer experiments, or long wait times for shared resources. At Yotta Labs, we believe infrastructure should enable discovery — not stand in its way. Today, we’re excited to announce the launch of the Yotta Labs Academic Research Support Program, an initiative designed to provide researchers with access to modern, production-grade AI infrastructure, backed by dedicated support and flexible pricing.
Research

Nov 12, 2025
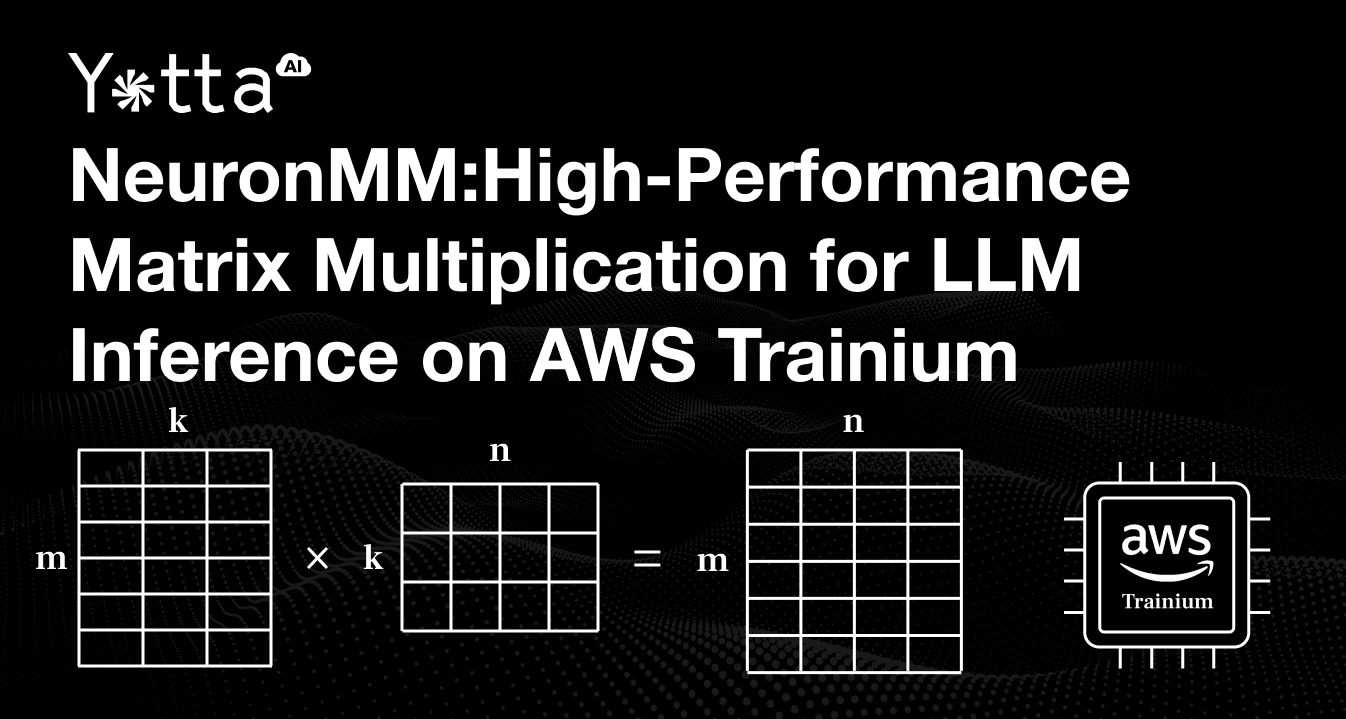
NeuronMM: High-Performance Matrix Multiplication for LLM Inference on AWS Trainium
Enabling high-performance of AI workloads on heterogeneous hardware is one of the major missions at Yotta Labs. Yotta Labs has explored various AI accelerators (such as NVIDIA GPU, AMD GPU, and AWS Trainium) to optimize performance and reduce production costs. Recently, our chief scientist Dong Li, leading a team of researchers, made significant breakthroughs in building high-performance matrix multiplication (matmul) for LLM inference on Trainium. Evaluating with nine datasets and four recent LLMs, we show that NeuronMM largely outperforms the state-of–the-art matmul implemented by AWS on Trainium: at the level of matmul kernel, NeuronMM achieves an average 1.35× speedup (up to 2.22×), which translates to an average 1.66× speedup (up to 2.49×) for end-to-end LLM inference. The code is released at https://github.com/PASAUCMerced/NeuronMM.
Research

Oct 23, 2025
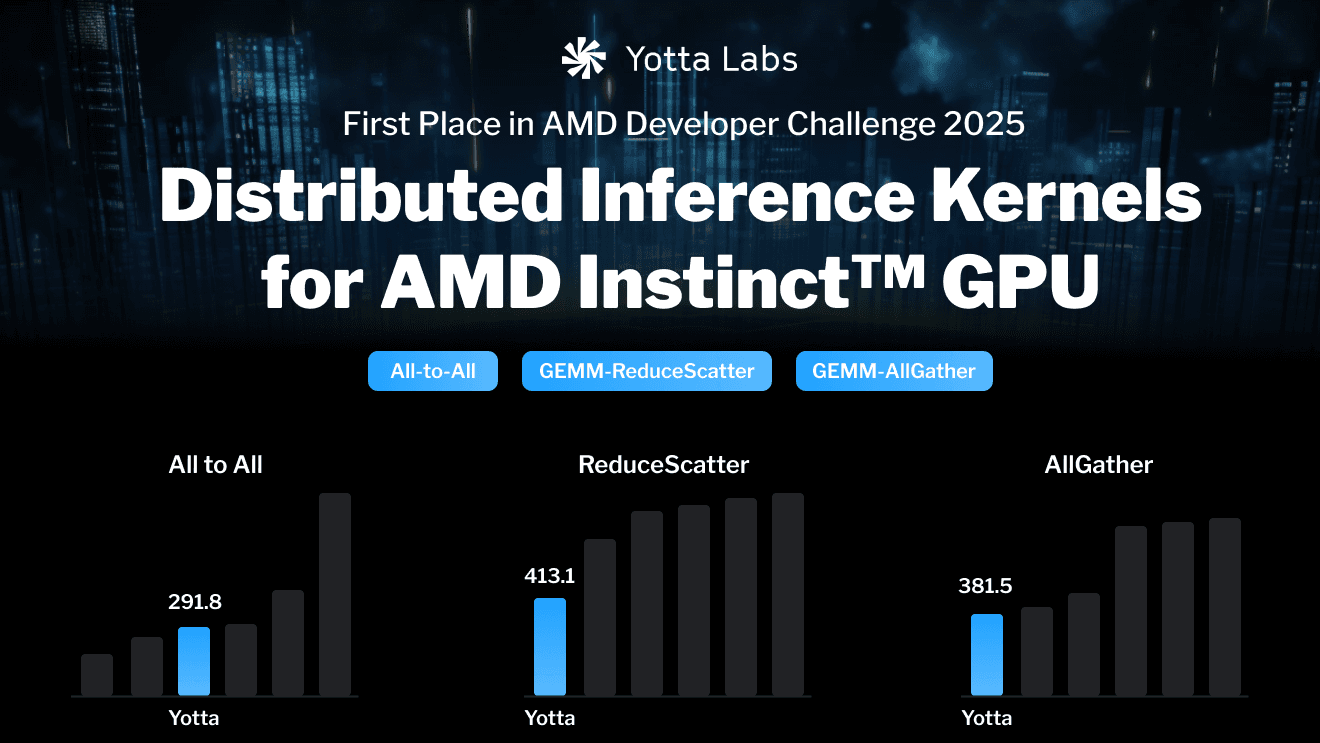
Optimizing Distributed Inference Kernels for AMD DEVELOPER CHALLENGE 2025: All-to-All, GEMM-ReduceScatter, and AllGather-GEMM
This technical report presents our optimization work for the AMD Developer Challenge 2025: Distributed Inference Kernels, where we develop high-performance implementations of three critical distributed GPU kernels for single-node 8× AMD MI300X configurations. We optimize All-to-All communication for Mixture-of-Experts (MoE) models, GEMM-ReduceScatter, and AllGather-GEMM kernels through fine-grained per-token synchronization, kernel fusion techniques, and hardware-aware optimizations that leverage MI300X's 8 XCD architecture. These optimizations demonstrate significant performance improvements through communication-computation overlap, reduced memory allocations, and ROCm-specific tuning, providing practical insights for developers working with distributed kernels on AMD GPUs.
Research

Oct 13, 2025
Performance Optimization for Reinforcement Learning on AMD GPUs
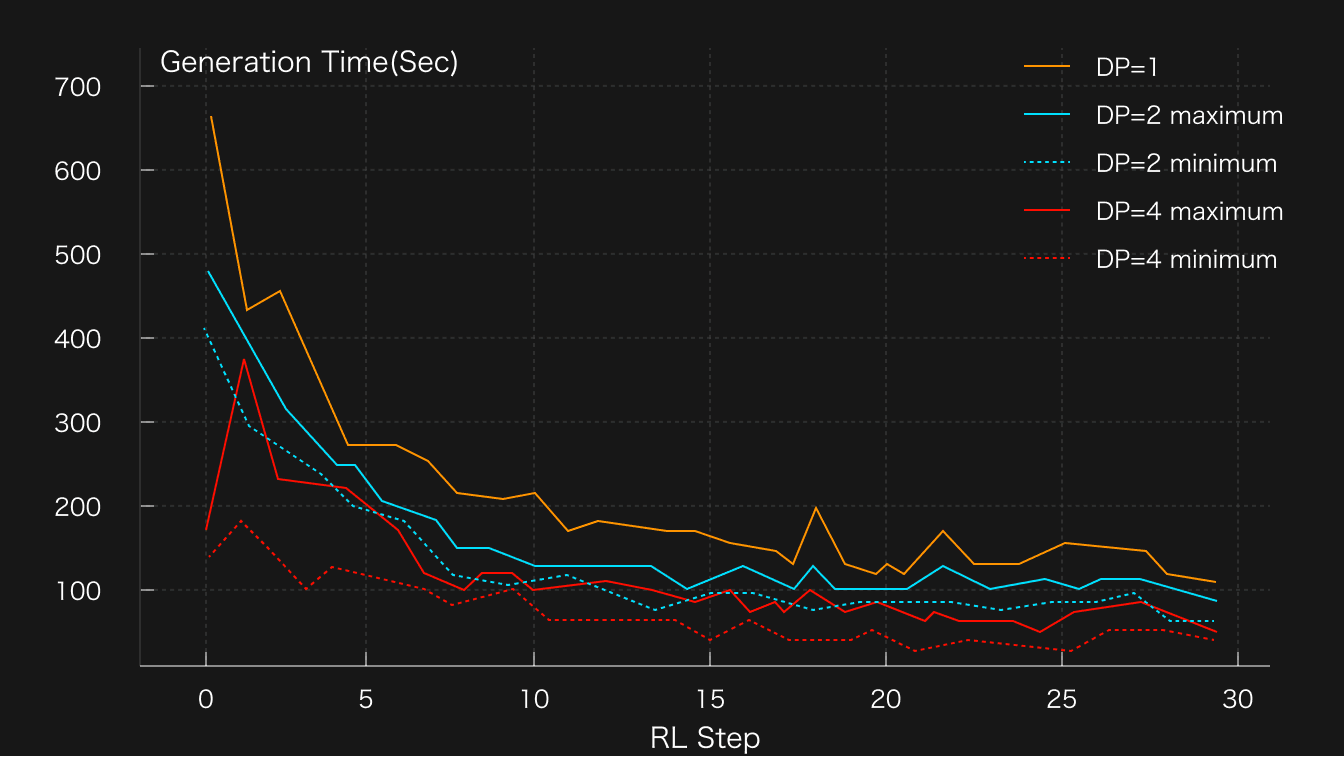
This blog presents our performance optimization and parameter tuning methodology for Reinforcement Learning (RL) workloads using the Verl framework on AMD’s MI300X GPU platform. By capitalizing on the MI300X’s 192GB of unified memory per GPU, we test and optimize the parallelism strategy to minimize the inter-GPU communication on the three phases in GPRO; we also explore the performance with various parallelisms and reveal the nontrivial relationship between the parallelism degree and performance.
News

Sep 23, 2025
NSF SBIR | Decentralized Artificial Intelligence (AI) Computing Operating System for Accessible and Cost-Effective AI
Yotta Labs Awarded Competitive Grant from the U.S. National Science Foundation to Advance Decentralized AI for Accessible and Cost-Effective Computing
Products

Nov 03, 2026
How to Generate a Video and Upscale It to 4K on the Yotta AI Gateway with Topaz Labs Starlight
Generate a clip with Wan 3.0, then send it to Topaz Labs Starlight for a 4K version, both on the Yotta AI Gateway with one API key. This walkthrough has the exact requests we used, the one command you need in between, and what the whole thing cost.
Cost Optimization
Inference

Nov 03, 2026
Seedance 2.5 API: Reference-to-Video with Real People, Limits, and Pricing
Seedance 2.5 on Yotta AI Gateway now accepts real people as reference subjects. Here is what the reference-to-video endpoint takes (up to 30 images, 10 videos, and 10 audio clips per request), what it costs by resolution, and how it compares to Seedance 2.0 and image-to-video.
Cost Optimization
Infrastructure

Nov 02, 2026
How to Monitor Latency Across AI APIs in Production
Monitor latency across AI APIs with application-side timing, time to first token, percentile metrics, request tags, traces, and actionable alerts.
Autoscaling
Distributed Inference
Infrastructure

Nov 02, 2026
Manage Rate Limits Across AI Model Providers
Manage AI provider rate limits with centralized traffic controls, token-aware throttling, queues, retry budgets, backpressure, and observability.
Autoscaling
Cost Optimization
Inference

Oct 30, 2026
Mistral Large 4 Hardware Requirements: GPU, Memory, and Which Checkpoint to Run
Mistral Large 4's weights are out: an FP8 checkpoint at 1.06 TB and an NVFP4 checkpoint at 610 GB, under a modified MIT license. Which GPU nodes fit each one, what the license allows, and how to serve it.
GPU Pods
Distributed Inference
Infrastructure

Oct 29, 2026
Detect Unusual Token Usage and API Cost Spikes
Detect unusual token usage and LLM API cost spikes with baselines, scoped alerts, usage attribution, and a practical investigation workflow.
Cost Optimization
Infrastructure

Oct 29, 2026
Track Token Usage by User, Team, or Feature
Track LLM token usage by user, team, customer, workspace, or feature with request-level records, stable attribution fields, and useful dashboards.
Cost Optimization
Inference

Oct 29, 2026
OpenAI API Alternatives: Claude, Gemini & Open-Source Models Compared
Looking for alternatives to the OpenAI API? Compare Claude, Gemini, open-weight models, and gateways that switch providers without code changes.
Cost Optimization
Distributed Inference
Infrastructure

Oct 27, 2026
Set Token Budgets for an AI Product
Set practical AI product token budgets by measuring usage, forecasting demand, applying alerts and caps, and reviewing limits by user, tenant, and feature.
Cost Optimization
Deep dives into multi-silicon AI optimization, infrastructure architecture, and the science behind Yotta's performance breakthroughs.